A recipe is data wearing the clothes of an article
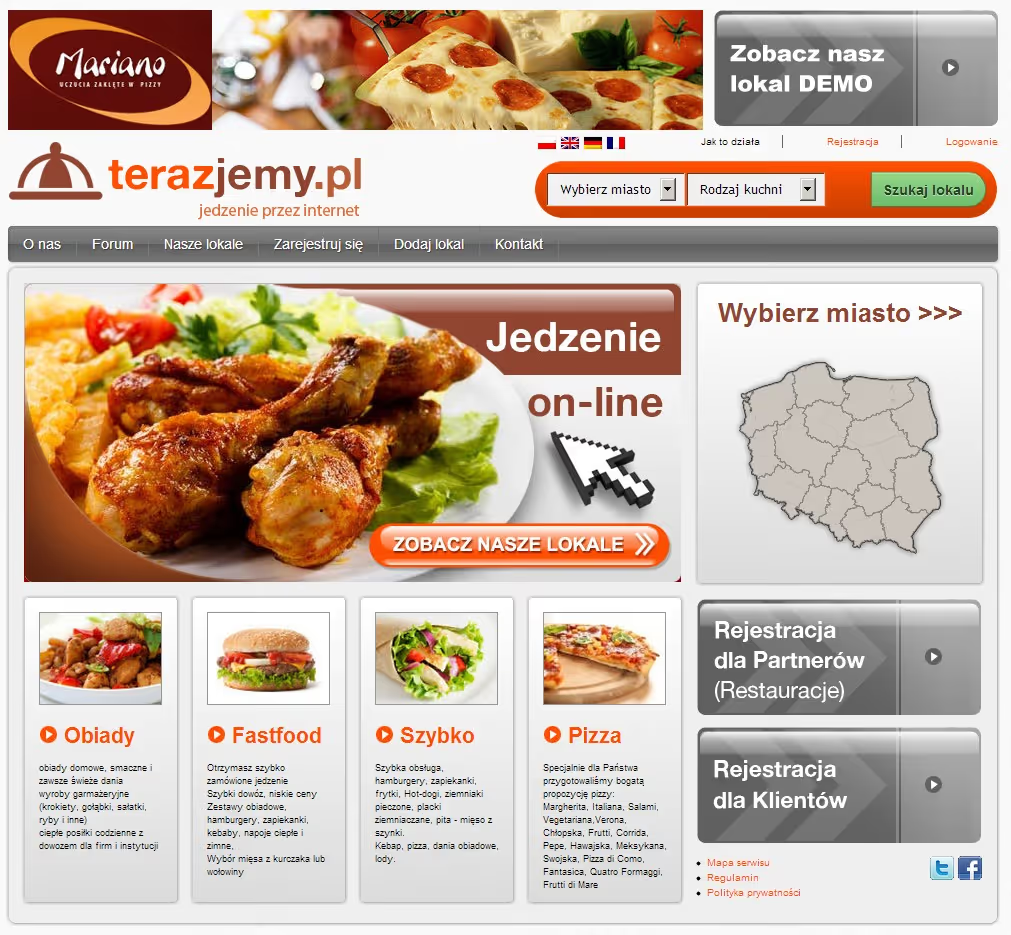
terazjemy.pl was a Polish healthy-eating site: recipes, guidance articles and educational material about nutrition and physical activity. The site has not been online for some time, so what follows describes design decisions rather than a current state. It was delivered in 2012 and the build ran about six weeks.
The decision that shaped everything else looks trivial from outside. A recipe resembles an article. It has a title, a photograph and a body of text, so the obvious move is to publish it as a post and stop thinking. It behaves nothing like an article, though. An article is read once, top to bottom, by one person sitting still. A recipe is read twice: once in the shop for the shopping list, once in the kitchen for the sequence of steps, and the second reading happens with messy hands and a screen that keeps dimming. An article has an author and a date. A recipe has a preparation time, a yield, a difficulty, a list of ingredients with quantities and a set of dietary labels, and every one of those is something people search on rather than decoration around the text.
So a recipe could not be an ordinary post with prose in it. It needed a structure of its own, where ingredients are list items carrying a quantity and a unit, steps are an ordered sequence, and time, yield and dietary categories live in separate fields. Only that structure answers a question of the shape “gluten-free dinner in under thirty minutes”, and only that structure can be described in a way a search engine genuinely reads.
Structured data has to come from the same place as the words
Recipes are one of the few content types search engines treat with a dedicated, detailed vocabulary. Ingredients, steps, preparation and cooking time, yield and nutrition all have a place in it, and a correctly described recipe surfaces differently from a plain article.
The important decision here is organisational rather than technical. Structured data is only worth having if it is generated from the same source as the visible content. When an editor types ingredients into a body of text while somebody else separately fills in fields for the search engine, those two sets drift apart within months, and they drift silently, because nobody reads structured data with their eyes. The recipe fields are therefore the only place anything is entered, and both the human view and the machine description are rendered from them.
The same principle heads off a second common mistake. A nutrition figure is a claim about a specific dish and depends on which products went into it. The field for it is therefore optional and stays empty until somebody deliberately fills it in. A field that helpfully pre-populates a calculated value produces something that looks like a measurement and is not one.
Units, and why they resist being tidied up
Once ingredients become list items, you have to decide what a unit is, and that is where an apparently clean data model meets a kitchen. Recipes do not speak in millilitres. English-language recipes mix cups, tablespoons, ounces and grams in the same list, a stick of butter means nothing outside North America, and a British oven instruction may still arrive as a gas mark rather than a temperature. Polish recipes carry their own version of this: alongside grams and millilitres they use a glass, a spoon, a pinch, and the dekagram, a unit essentially nobody outside Polish home cooking uses and which sits perfectly normally in an older recipe.
There are two obvious ways to handle it and both cost something. Force everything metric and you get consistent data and recipes that read like laboratory procedure. Leave the units exactly as written and you get natural language and no way to scale anything automatically.
We took a third route. The unit is a field chosen from a closed list, and where a conversion to metric exists it is recorded alongside. The recipe then displays the way its author wrote it, while the portion-scaling feature works wherever it has something to work with and openly declines where it does not.
Scaling itself looks trivial and is rarely done properly. Doubling the yield does not double the baking time and does not double a pinch of salt. A mechanism that multiplies everything by two produces recipes that cannot be cooked, so only entries carrying a numeric quantity and a measurable unit are recalculated, while times and descriptive instructions are left alone.
Traffic in a food site follows a calendar
A recipe site does not receive even traffic. It has sharp seasonal peaks, and a Polish site has one that dwarfs the others: Christmas Eve, with sudden demand for dishes nobody looks for during the other eleven months. A second peak lands in early January, where the dish stays the same and the intent changes, because people are looking for lighter versions of the food they just ate.
Two things follow. The first is a capacity question, and it is narrower than it sounds. Load does not spread across the year, so a configuration that is comfortable in March may not be in the week before Christmas, and the pressure lands on a dozen specific addresses rather than on the whole site. A narrow stream of traffic onto a handful of pages is dangerous and also easy to prepare for, because those same pages can be warmed in the cache in advance.
The second is editorial. Seasonal material that sits idle for a year is dormant, not dead, so removing it after the season is a mistake. Seasonal recipes keep a first-published date and a last-updated date, and during the window when people search for them they return to visible positions through topical links rather than through republishing the same text under a fresh date.
Photographs are the payload
A photograph of a dish is content here, not illustration. A recipe without one barely functions, because the reader decides with their eyes before reading a single ingredient. Food photographs are also unusually expensive to transmit: they are full of texture, short on flat areas, compress badly, and frequently come in several shots.
Performance work therefore went where the mass was. Files are processed on upload into the sizes that actually appear: the listing tile, the main recipe image, occasional step photographs. A listing thumbnail is never the main image scaled down by the browser, because scaling in the browser saves pixels and not bytes, and bytes are what the reader waits for.
Images below the first screen load as they approach the viewport. It is worth marking the limit of that technique, because it gets applied without thought. The main recipe photograph is usually the most important element of the first screen, so deferring that particular image makes the page feel worse rather than better. Lazy loading belongs below the fold, not on the element the reader is waiting for.
The newsletter, and the part that is not the form
The site collected addresses for a newsletter. This is where projects most often take a shortcut, because a field and a button can be built in fifteen minutes, and everything difficult is underneath.
An address typed into a form is a statement, not consent. Until it has been confirmed by clicking a link in a message, nobody even knows whether it belongs to the person who typed it. Sign-up is therefore two-stage: submitting the form creates a pending record, and only confirmation turns that into a subscription. Without that step anybody can sign up somebody else’s address, and the list grows by entries that turn into abuse reports on the first send.
The exit matters as much as the entrance. An unsubscribe link has to work without a login and without a form, in one click, because every obstacle placed on that path moves the unsubscribe into the spam button of a mail client, and that costs far more than losing one address.
Sending cannot happen inside a user’s request either. Delivery to a list takes time and fails in ways that have nothing to do with the person sitting in front of the form. Work of that kind goes into a queue and runs outside the request, with retries, because a mail server refusing once should not mean the message is gone.
What is actually being cached
A content site is a kind case for caching: almost everything it shows is identical for every visitor and changes rarely. The gain comes mostly from a request for an existing recipe never reaching PHP at all.
The elements that genuinely change are few and can be listed: a comment count, a latest-posts block, the logged-in state. Each of them, if embedded directly in the document, invalidates the cache for the whole page. So they are separated out and fetched independently, which sounds like added complexity and is the opposite: it lets the rest of the page stay cached for a long time instead of being rebuilt every time somebody leaves a comment.
Redis handles the layer underneath, the query results that recur across many pages: category listings, relationships between recipes, dietary tag aggregates. None of those is expensive on its own. All of them are computed on every view, and that kind of cost only appears under traffic, never on a clean test installation.
Invalidation is harder than population in this arrangement. Publishing one recipe changes not only its own page but the category listing, the home page, related blocks and the sitemap. Clear only the first and the rest of the site pretends for an hour that the recipe does not exist. Clear everything and every publication throws away the cache for the entire site. The sane middle is to clear what actually depends on the changed object, and that dependency has to be written out explicitly during the build, because no mechanism knows it by default.
Backups and the thing nobody checks
Backups ran automatically and were stored away from the site’s own server, with versioning, so that it was possible to return not only to the state before an outage but to the state before an editorial mistake made three days ago. Those are two different scenarios and only the second one happens often.
One point bears repeating because case studies usually leave it out. A backup nobody has ever restored is a hypothesis rather than a safeguard. The restore has to be performed at least once, on a separate environment, to learn how long it takes and what is missing from it, because gaps in a backup have a habit of revealing themselves only during a restore.
Maintenance, and directions that were never built
Ongoing care covered core, theme and plugin updates, log review, index monitoring and tidying database queries that grew alongside the recipe count. Testing ran on an environment holding a copy of real data, because a site with several hundred recipes and heavy taxonomies behaves nothing like a clean install with a demo theme.
A meal planner, an integration with diet-tracking applications and a community section were discussed as directions. None of them was built, and they are written here as directions rather than features for that reason. Each would also have changed the nature of the project: a meal planner introduces data belonging to a named individual, a diet-app integration introduces a dependency on somebody else’s interface, and a community section introduces moderation, which is continuous human work that a content site had not needed until then.
What carries forward
The method carries: treating a recipe as data rather than prose, generating the human view and the structured description from one source, separating stable content from volatile fragments when planning a cache, queueing anything that leaves the site, and testing against a copy of production.
The content model does not carry. It was shaped around one editorial team and one brief in the Strony www category. The recipe field set reflects that team’s decisions, and the dietary label set is a subject-matter judgement rather than a technical one. The next build starts with a scope analysis, and the quote follows it.
Frequently asked questions
Practical answers to apply the topic in real execution.
What scope did the terazjemy.pl project cover?
#How did delivery run for terazjemy.pl?
#What was the hardest technical part of terazjemy.pl?
#What part of terazjemy.pl could be reused on another build?
#Need an FAQ tailored to your industry and market? We can build one aligned with your business goals.
Let’s discuss