Introduction
Greg Ziółkowski’s merge proposal to put a wp_knowledge custom post type and AI Guidelines into WordPress 7.1 sparked a real debate. Creators wanted a standard place to store rules for human writers and AI tools. Critics, including 9seeds owner Jon Brown, said it should live as a plugin first.
Neither change landed. Matt Mullenweg vetoed the Guidelines merge in July. The Classic block hide-from-inserter plan was reversed the same month. WordPress 7.1 Mary Lou shipped on 19 August without wp_knowledge, without Guidelines, and with the Classic block still in the inserter. The rest of this article is the proposal as it stood, plus what to do now that core did not take it. The PHP and React snippets below are a plugin-shaped sketch, not a core API.
What is the wp_knowledge post type in WordPress
The goal of Greg Ziółkowski’s proposal is to define a dedicated section in the core to store website guidelines, brand voices, and content structures. This standardized data under wp_knowledge is intended for:
- For writers: site owners write the standards once on a Guidelines page under Settings, and new writers read them in one place instead of a PDF.
- For AI tools: any tool with the right permissions can read these records through the REST API and align generated text with the site’s style. The proposal ships no AI provider, model or retrieval algorithm of its own.
However, some developers argue that the change is premature and prefer a trial run as an independent feature plugin before a final core merge.
How wp_knowledge differs from traditional guidelines
Here is how storing editorial rules changes:
| Feature | Traditional approach (still current after 7.1) | Proposed wp_knowledge model (did not ship) |
|---|---|---|
| Storage location | External PDFs, static pages | Dedicated custom post type wp_knowledge |
| API support | None or custom | REST routes under /wp/v2/knowledge, authenticated reads |
| Editor integration | Manual review by the author | A Guidelines settings screen; no automatic enforcement |
| AI processing | Hard (requires scraping) | Records any permitted consumer can read; no AI provider in core |
| Brand voice | Third-party plugins required | A Copy scope for tone, voice and vocabulary; validation left to plugins |
What the merge proposal specified for wp_knowledge
The merge proposal describes Knowledge as “a general primitive for storing author-facing and agent-facing site knowledge as standard WordPress content”. It reuses parts WordPress already has: a custom post type, a taxonomy, roles and capabilities, revisions and REST. The experimental code in Gutenberg matches the proposal:
- The post type
wp_knowledgeis registered withpublicset to false and no native admin screens. Records never appear in front-end queries. - A taxonomy,
wp_knowledge_type, says what a record is. Core defines three types:guideline(a standard that is the source of truth),memory(durable context a user saved or approved) andnote(private working text). A record saved without a type falls back tonote. Plugins add types through thewp_knowledge_typesfilter. - The Guidelines screen is built from scopes: Site, Copy, Images and Blocks. Each scope is a
guidelinerecord with a reserved slug such asguideline-copy, and plugins can register more. - REST lives under
/wp/v2/knowledge, with a read-only registry at/wp/v2/knowledge/guideline-scopes. Collection reads require authentication. - New records default to
private. Revisions are kept and autosave is switched off, because the records have no editor session.
Capabilities follow a *_knowledge_items namespace. The access policy from Gutenberg PR 78296, as listed in the proposal:
| Role | Site-wide guidelines | Own private records | Other users’ private records | Manage global records |
|---|---|---|---|---|
| Subscriber | No | No | No | No |
| Contributor | Read where capabilities allow | Create, read, edit, delete | No | No |
| Author, Editor | Read where capabilities allow | Create, read, edit, delete | No | No |
| Administrator | Manage | Yes | Yes | Yes |
The Guidelines screen itself still requires manage_options. Because nothing in wp_knowledge is public, a crawler never sees it. A publishingPrinciples link in your schema has to point to a public page.
How Guidelines moved from Gutenberg 22.7 to a vetoed core merge
The name and storage changed twice before the veto. Guidelines landed as an experiment in Gutenberg 22.7, described on 23 March 2026 by Aagam Shah. You switched it on under Gutenberg, Experiments, and a Guidelines page appeared under Settings with sections for Site, Copy, Images, Blocks and Additional rules, plus export to guidelines.json, import and revision history. Storage was a post type called wp_content_guideline, with each category in post meta and REST at /wp/v2/content-guidelines. That post states that Guidelines “intentionally focuses on capture and retrieval” and does not enforce rules or generate content.
On 22 June Greg Ziółkowski published the merge proposal for 7.1, with the core patch in wordpress-develop PR 12201 (Trac ticket 65476). Gutenberg PR 79149, merged on 29 June, renamed the storage to wp_knowledge. On 10 July Anne McCarthy posted the decision in the proposal comments after a review with Matt Mullenweg: the work would not proceed for 7.1, and core should not take things “not already driven by real-world adoption with impressive week to week growth (think: double digits)”. Beta 1 followed on 15 July.
What happened next is visible on GitHub. Ziółkowski opened WordPress/ai PR 949 on 18 August to port the experiment into the AI plugin. He closed it unmerged on 1 October, after maintainers said AI plugin experiments should rely on Gutenberg experiments instead of duplicating them. As of 14 October 2026, PR 12201 is still open and the 7.1 branch of wp-includes/post.php contains no wp_knowledge. The feature exists only behind the Gutenberg experiment flag.
Is the Classic block removed in WordPress 7.1
A plan to hide the Classic block from the inserter in 7.1 was reversed. Marin Atanasov wrote on 7 July that the original approach “had things largely backward”. The block is still there. Do not run a mass conversion because you think 7.1 started a clock.
If you still want to convert Classic (core/freeform) content on your own schedule, here is a WP-CLI pattern and a cleanup filter. Test on a copy of the database first. Replacing the freeform delimiter with a paragraph delimiter is a blunt instrument and will mangle mixed HTML.
Run the following command on the server:
# Find and convert classic editor block to paragraph blocks
wp db query "UPDATE wp_posts SET post_content = REPLACE(post_content, '<!-- wp:freeform -->', '<!-- wp:paragraph -->') WHERE post_content LIKE '%<!-- wp:freeform -->%'"
Additionally, add a utility function in your theme’s functions.php to clean up legacy TinyMCE leftovers:
<?php
/**
 * Fallback and clean-up utility for legacy Classic block outputs
 */
function wppoland_clean_legacy_classic_blocks($content) {
    if (has_block('core/freeform', $content)) {
        $content = str_replace('<!-- wp:freeform -->', '<!-- wp:paragraph -->', $content);
        $content = str_replace('<!-- /wp:freeform -->', '<!-- /wp:paragraph -->', $content);
    }
    return $content;
}
add_filter('the_content', 'wppoland_clean_legacy_classic_blocks', 9);What replaces the Classic block hide in WordPress core
The 7 July post says the hide did not bring the project closer to not loading TinyMCE, and states the principle that “the Classic block should become obsolete by choice, not by force”. It also removed the block-level deprecation notice, brought back the “Convert to blocks” toolbar action, and dropped the wp_classic_block_supports_inserter filter, which never shipped in a stable release. The Enable Classic Block plugin is being closed, so you can deactivate it.
The post lists the work that replaces the hide:
- learn why people still rely on Classic and close those gaps,
- make “Convert to blocks” reliable, since it still has flaws and inconsistencies,
- build better conversion and migration tools, including mass migration,
- improve how TinyMCE assets are registered and allow them to be disabled,
- give plugins a way to declare an explicit TinyMCE dependency,
- explore loading TinyMCE on demand or asynchronously,
- stop loading TinyMCE in the block editor when the Classic block is disabled in the block manager.
You can confirm the 7.1 state in the source: the core/freeform block.json on the 7.1 branch has no inserter: false support flag. The last item is listed as future work, so do not expect that disabling the Classic block in the block manager removes TinyMCE from the 7.1 editor.
How to add wp_knowledge data to JSON-LD schema
Implementing a knowledge post type yourself, as a plugin, is still a useful tool for Answer Engine Optimization. It is not a 7.1 core feature. In the era of Perplexity or ChatGPT Search, websites must serve information clearly. Storing official corporate details in a structured post type simplifies generating rich Schema.org metadata.
For example, I can write a filter to include data from wp_knowledge as about or mentions objects in the page’s JSON-LD schema:
<?php
// Automatically append wppoland_knowledge metadata to JSON-LD schema
add_action('wp_head', 'wppoland_append_knowledge_schema');
function wppoland_append_knowledge_schema() {
    if (is_single()) {
        $knowledge = get_posts(['post_type' => 'wppoland_knowledge', 'numberposts' => 1]);
        if (!empty($knowledge)) {
            $schema = [
                "@context" => "https://schema.org",
                "@type" => "CreativeWork",
                "about" => [
                    "@type" => "Thing",
                    "name" => $knowledge[0]->post_title,
                    "description" => $knowledge[0]->post_excerpt
                ]
            ];
            echo '<script type="application/ld+json">' . json_encode($schema, JSON_UNESCAPED_SLASHES) . '</script>';
        }
    }
}
I can also register custom metadata for wp_knowledge:
<?php
add_action('init', 'wppoland_register_knowledge_meta');
function wppoland_register_knowledge_meta() {
    register_post_meta('wppoland_knowledge', 'wikidata_qid', [
        'show_in_rest' => true,
        'single' => true,
        'type' => 'string',
        'sanitize_callback' => 'sanitize_text_field'
    ]);
}
When AI crawlers index the website, they immediately get a structured, authoritative summary of facts, which increases the brand’s visibility in direct search answers.
How an editorial policy in Schema.org supports E-E-A-T
The integration of editorial guidelines directly in the WordPress core via wp_knowledge is no coincidence. In 2026, search engines, and especially Google, place unprecedented emphasis on E-E-A-T criteria. Publisher trustworthiness and transparency in content creation are now key ranking factors.
Previously, author boxes or about pages were manually updated. Today, Google’s automated systems search for deeper semantic links. They want to know if there is an editorial policy (editorial policy) and how facts are verified.
wp_knowledge structures this information at the system level. A dedicated post type for ethical standards, expert teams, and research methodologies becomes part of the site’s knowledge graph. SEO plugins can link these rules to authors via the publishingPrinciples attribute in Schema.org. Because the proposed records are private, that link has to point to a public page that publishes the same policy. This signals to search engines that the content is the result of a careful editorial process and not blindly generated by an AI.
Additionally, Answer Engines construct direct relationships between distinct entities. Linking authors, editorial processes, and validated content via structured JSON-LD dramatically boosts the trust score of the entire site in AI search models.
How to check posts against wp_knowledge rules before publishing
To automate quality control in a B2B agency, developers can use the following PHP filter to validate posts against the wp_knowledge guidelines before publication:
<?php
add_action('transition_post_status', 'wppoland_enforce_knowledge_rules', 10, 3);
function wppoland_enforce_knowledge_rules($new_status, $old_status, $post) {
    if ($new_status === 'publish' && $post->post_type === 'post') {
        $rules = get_posts(['post_type' => 'wppoland_knowledge', 's' => 'brand-voice']);
        if (!empty($rules)) {
            $excerpt = $rules[0]->post_excerpt;
            if (!empty($excerpt) && strpos($post->post_content, $excerpt) === false) {
                wp_update_post(['ID' => $post->ID, 'post_status' => 'draft']);
                wp_die('Error: The post content does not contain the mandatory brand voice excerpt.');
            }
        }
    }
}
React Sidebar Component for Gutenberg editor:
import { registerPlugin } from '@wordpress/plugins';
import { PluginSidebar } from '@wordpress/edit-post';
import { useState, useEffect } from '@wordpress/element';
import { select } from '@wordpress/data';

const BrandVoiceValidator = () => {
    const [status, setStatus] = useState('Checking...');
    useEffect(() => {
        const unsubscribe = select('core/editor').subscribe(() => {
            const content = select('core/editor').getEditedPostContent();
            if (content.includes('best') || content.includes('guarantee')) {
                setStatus('Warning: Violates brand guidelines.');
            } else {
                setStatus('Compliant: Tone of voice matches guidelines.');
            }
        });
        return () => unsubscribe();
    }, []);
    return (
        <PluginSidebar name="brand-voice-sidebar" title="Brand Voice" icon="admin-users">
            <div style={{ padding: '16px' }}>
                <h4>Guideline Validation</h4>
                <p>{status}</p>
            </div>
        </PluginSidebar>
    );
};
registerPlugin('brand-voice-validator', { render: BrandVoiceValidator });
And the complete PHP plugin file structure for registering the post type:
<?php
/**
 * Plugin Name: WPPoland Custom Knowledge Base and AI Guidelines
 * Description: Registers the wppoland_knowledge custom post type
 * Version: 1.0.0
 */

namespace WPPoland\Knowledge;

class KnowledgeBasePlugin {
    private static $instance = null;
    public static function get_instance() {
        if (null === self::$instance) { self::$instance = new self(); }
        return self::$instance;
    }
    private function __construct() {
        add_action('init', [$this, 'register_post_type']);
    }
    public function register_post_type() {
        register_post_type('wppoland_knowledge', [
            'public' => true,
            'label'  => 'Knowledge',
            'show_in_rest' => true,
            'supports' => ['title', 'editor', 'excerpt']
        ]);
    }
}
add_action('plugins_loaded', function() { KnowledgeBasePlugin::get_instance(); });How Gutenberg block validation and deprecations work
The Classic block is not being removed in 7.2 on the strength of this cycle. Block deprecation schemas still matter for your own blocks. Here is how Gutenberg matches saved HTML to a save() function, which is useful whether or not core ever hides core/freeform.
1. Gutenberg block validation API under the hood
When a post loads in the Gutenberg block editor, the JS engine parses the saved HTML comments in wp_posts.post_content. It executes the block’s current save() function and compares the generated output against the raw HTML string stored in the database.
If the database contains:
<!-- wp:wppoland/custom-block -->
<div class="wp-block-wppoland-custom-block legacy-class">Content</div>
<!-- /wp:wppoland/custom-block -->
But the block’s current implementation outputs new-class, a validation error occurs. Gutenberg prompts the user with a warning about block corruption and provides conversion buttons.
2. Re-registering legacy block structures in React (deprecations)
To prevent block validation errors, register previous versions of the block in the deprecated configuration array. Gutenberg will attempt to match these schemas in order if the primary validation fails:
import { registerBlockType } from '@wordpress/blocks';

registerBlockType( 'wppoland/custom-block', {
    title: 'Custom Block',
    attributes: {
        content: { type: 'string', source: 'html', selector: 'div' }
    },
    edit: ( { attributes } ) => <div className="new-class">{ attributes.content }</div>,
    save: ( { attributes } ) => <div className="new-class">{ attributes.content }</div>,
    deprecated: [
        {
            attributes: {
                content: { type: 'string', source: 'html', selector: 'div' }
            },
            save( { attributes } ) {
                return <div className="legacy-class">{ attributes.content }</div>;
            }
        }
    ]
} );3. Programmatic block parsing in PHP (parse_blocks)
At the server level, WordPress uses parse_blocks() to deserialize the post content back into a structured array of block objects. The parser reads block delimiters, decodes attribute JSON payloads, and returns a hierarchical tree:
<?php
$blocks = parse_blocks( get_post( 123 )->post_content );
foreach ( $blocks as $block ) {
    if ( $block['blockName'] === 'wppoland/custom-block' ) {
        $content = $block['attrs']['content'] ?? "";
    }
}
This architecture keeps B2B client sites highly performant, stable, and easily maintainable when performing massive block-level migrations.
How to build a wp_knowledge plugin for several desks
wp_knowledge is not in 7.1. If you need structured editorial rules for humans and agents, you register your own post type in a plugin. The sketch below is that plugin shape. It is not a client case study and it is not a core API.
The prefix matters. The plugin handbook on custom post types says: “To ensure forward compatibility, do not use wp_ as your identifier”. The Gutenberg experiment registers wp_knowledge only if that post type does not exist yet, so a plugin that claims the same name first replaces a private store with whatever settings the plugin chose, including public set to true. The sketch below uses wppoland_knowledge for that reason.
Newsrooms that already keep style rules in PDFs still have the same problem they had before 7.1: editors check drafts by hand, and external generators have no official place to read the rules.
A plugin-shaped workflow
- Structured knowledge nodes: I defined specific
wppoland_knowledgecustom posts containing editorial guidelines for different desks (news, finance, sports). These rules were stored as structured JSON schema payloads. - REST API distribution for AI tools: I exposed a secure REST API endpoint, allowing external content generation pipelines to fetch localized formatting constraints dynamically:
curl -H "Authorization: Bearer [TOKEN]" https://portal.wppoland.dev/wp-json/wp/v2/wppoland_knowledge?category=brand-voice - Real-time Gutenberg sidebar auditor: I developed a React component in the block editor sidebar. It subscribed to document changes and automatically highlighted any vocabulary or phrasing that violated the active desk guidelines.
- Programmatic WP-CLI quality checks: I deployed a cron script using WP-CLI to audit published posts against guidelines and flag exceptions for senior editor review.
None of that requires a core post type. It requires a plugin you own, with permissions and a REST surface you can version. That is the outcome the veto pointed at: prove adoption outside core first.
Is wp_knowledge useful for AEO on B2B sites
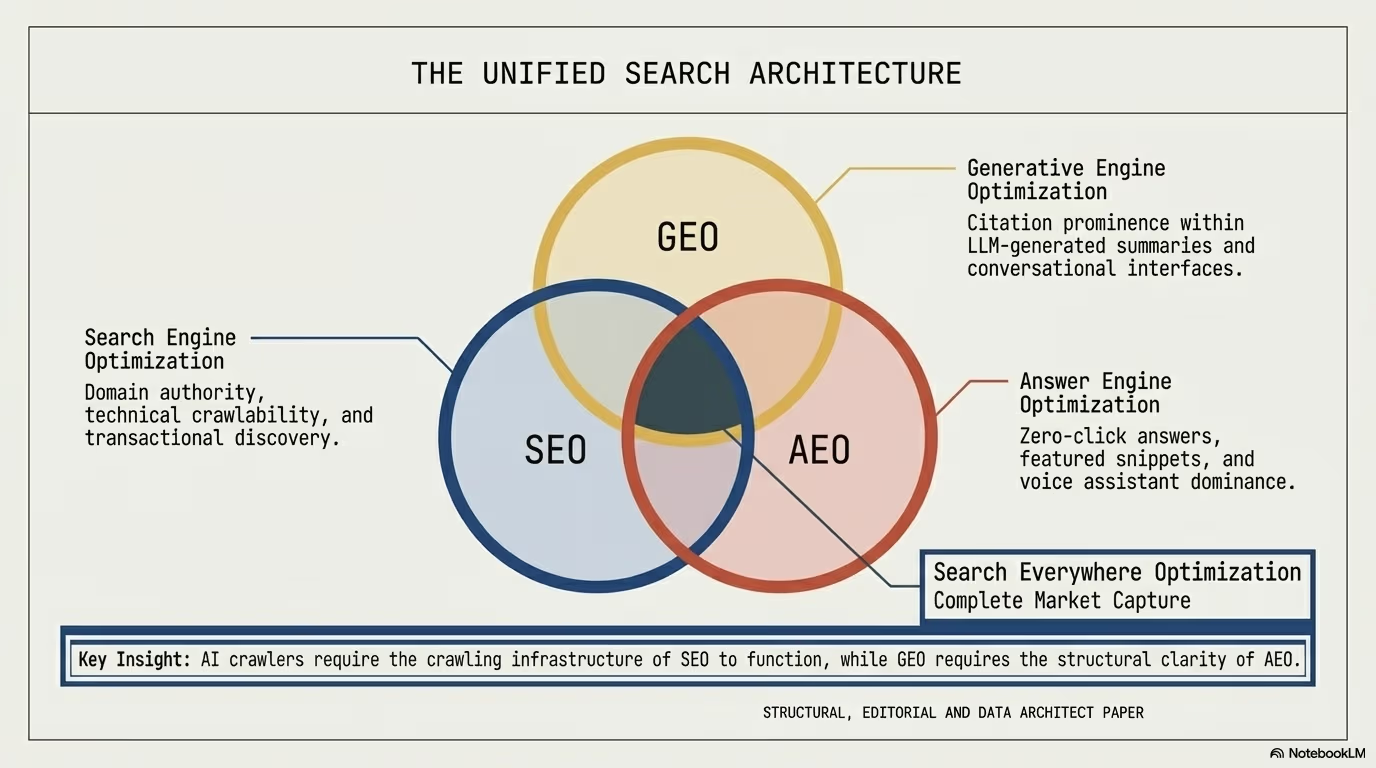
A native wp_knowledge post type in core would have been a useful step for the AI era. It is not in 7.1. The veto left the work as an experiment in Gutenberg. As search behavior shifts from traditional query links to Answer Engines (such as Perplexity, Claude, and Gemini), the discipline of SEO is evolving into Answer Engine Optimisation (AEO).
Enterprise B2B developers and publishers can no longer write copy solely for human readability or basic keyword indexers. They must deliver structured, verifiable, and machine-readable data payloads that AI models can consume to construct accurate answers.
Why structured guidelines matter for B2B site visibility
- E-E-A-T verification (trust signals): Answer engines favor highly transparent and authoritative sources. Editorial policies, expert bios and verification workflows help only when they are published on public pages that AI bots can tie to active authors. Records in the proposed
wp_knowledgestore are private, so they would feed your own tools, not the crawlers. - Schema.org principles integration: Data points from
wp_knowledgecan be automatically mapped by SEO tools to the Schema.orgpublishingPrinciplesproperty. This signals a high-quality editorial pipeline to AI crawlers. - Do not bank a Core Web Vitals win on Classic block deprecation. That hide did not ship. If you want TinyMCE off the editor path, that is still your plugin and theme work, not a 7.1 free lunch.
If you need structured guidelines on a client site, register your own post type. Do not wait for core to reverse the veto.
What to do after updating to WordPress 7.1
- Do not mass-convert Classic blocks because of this release. The inserter still offers them.
- Audit Classic usage only when you next touch that content, so you know the debt.
- Do not look for
wp_knowledgeon a 7.1 site. It is not there. If you need the storage, ship a plugin. - Test the iframed post editor, which did ship. Custom blocks that assume a global
documentwill break. See the iframed editor note. - Keep Guidelines in Gutenberg if you already use the experiment. Do not promise clients a core settings screen.
Summary
WordPress 7.1 Mary Lou shipped without wp_knowledge and without Guidelines. The merge was vetoed. The Classic block is still in the inserter. The useful 7.1 work for agencies is elsewhere: responsive styling, client-side media, and the always-iframed editor. If you still want structured editorial rules for agents, build the plugin. Do not write it into a 7.1 upgrade plan as if core took it.